
No prompt makes an answer true
Only a check outside the model can. Here are the errors that show up when it runs, on documents and on code, each one backed by its source.
What to expect: posts about documents and about code, each with a real error and the check that caught it. Every number stands with its source.
The principle: quality engineering instead of prompt engineering, true for documents, code and translation.
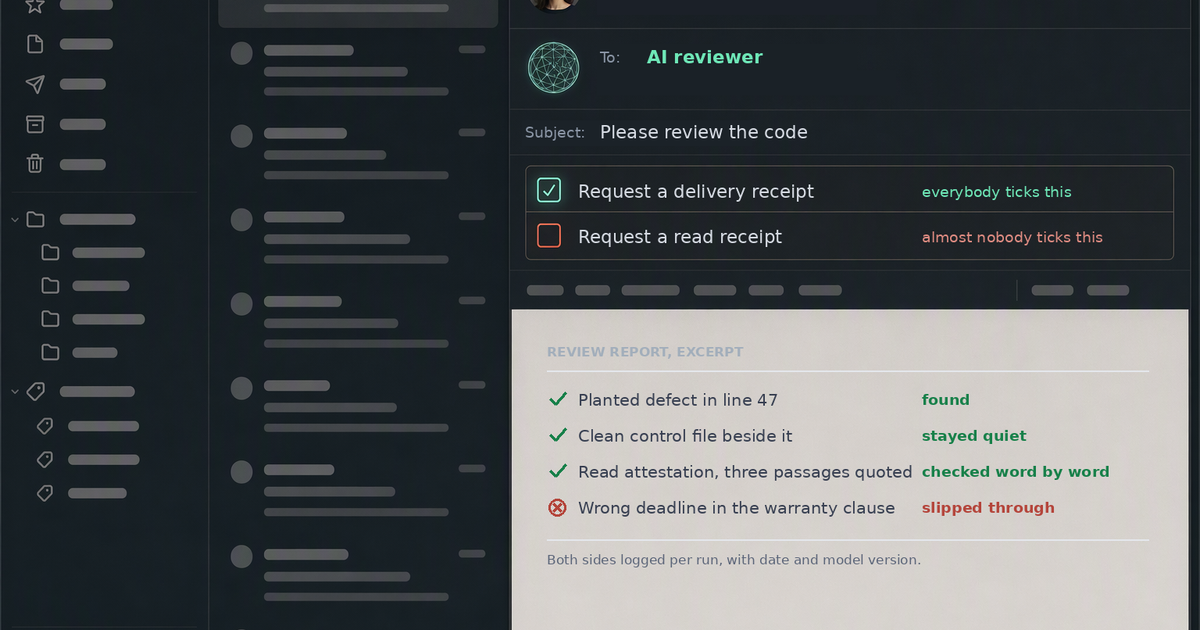
Your AI review has never seen a real defect
A second AI step checks the first one's work. None of the large projects measures whether that review fires at all. The manufacturing answer, plus the three steps that close the gap.
25 August 2026 · 8 min
 AI in general
The manifesto of the lean software factory
Eleven Lean Production and Toyota mechanisms, from 5S to Jidoka, Poka-Yoke, Kanban and Kaizen, carried over to catching and blocking Goodhart-style tricks in AI coding agents.
20 August 2026 · 10 min
 AI in general
Why the results of reasoning models still need checking
Reasoning raises the hit rate and stays probabilistic. Three findings from published research and the three places a check can sit.
19 August 2026 · 10 min
 AI in general
Skills, prompts, hacks: all of it is useless without automatic checks
Prompt formulas, skill lists, AI hacks: nearly every tip improves the input. Whether the result can be trusted is decided by checking the output. Here is the filter question plus the first step to your own check.
18 August 2026 · 5 min
 AI in general
The hot hand is real: in cards, in sport and in AI
A run at the card table is more than a story the brain tells. The same feedback loop pulls an AI model up or down.
17 August 2026 · 10 min
 AI in general
Spec-driven development with AI: the honest version
Four measured findings, four toolkits and the failure modes practitioners report. What the evidence carries and what it does not.
16 August 2026 · 19 min
 AI in general
The ironies of automation: why the human above the agent matters more
Bainbridge's ironies of automation applied to AI coding agents with research from 2023 to 2025 and four consequences for spec coding.
15 August 2026 · 6 min
 AI in general
The 15 biggest prompting myths and why your system prompt will not save your product
Fifteen beliefs about prompting, each measured against the research. Seventeen sources, one conclusion.
14 August 2026 · 15 min
 AI in general
The whack-a-mole game in prompt engineering: why fixing does not last
One error fixed, the next one up somewhere else. Four papers on why prompt patching never converges.
14 August 2026 · 4 min
 AI in general
Critical document reviews with AI: how hardware engineers nip false figures in the bud
A datasheet says 2.7 volts, the AI summary says 3.3. How to catch an invented figure before it reaches your design review.
07 August 2026 · 4 min
 AI in general
Manufacturing discipline, not prompt engineering: poka-yoke, MSA, FMEA for AI code
Poka-Yoke, MSA and FMEA applied to AI-generated code. Quality engineering instead of prompt engineering.
07 August 2026 · 14 min
 AI in general
No More Hallucinations or Half-Baked Output: How to Dramatically Elevate Your AI's Quality
One checker file forces every claim to carry evidence and exposes both invented statements and half-read documents.
06 August 2026 · 10 min
 AI in general
The seven failure dimensions of AI review: mechanism and control
Seven dimensions in which AI review fails, each with its mechanism and the control that holds it.
06 August 2026 · 19 min